Your Incident Doesn't Fit in 1M Tokens
AI-powered incident analysis sounds compelling until you do the math. A 1M-token context window holds roughly 5,000 OpenTelemetry spans. A real incident generates 9 million. This post breaks down the arithmetic and explains why the bottleneck isn't the model, it's the instrumentation, sampling, and retention pipeline that feeds it.
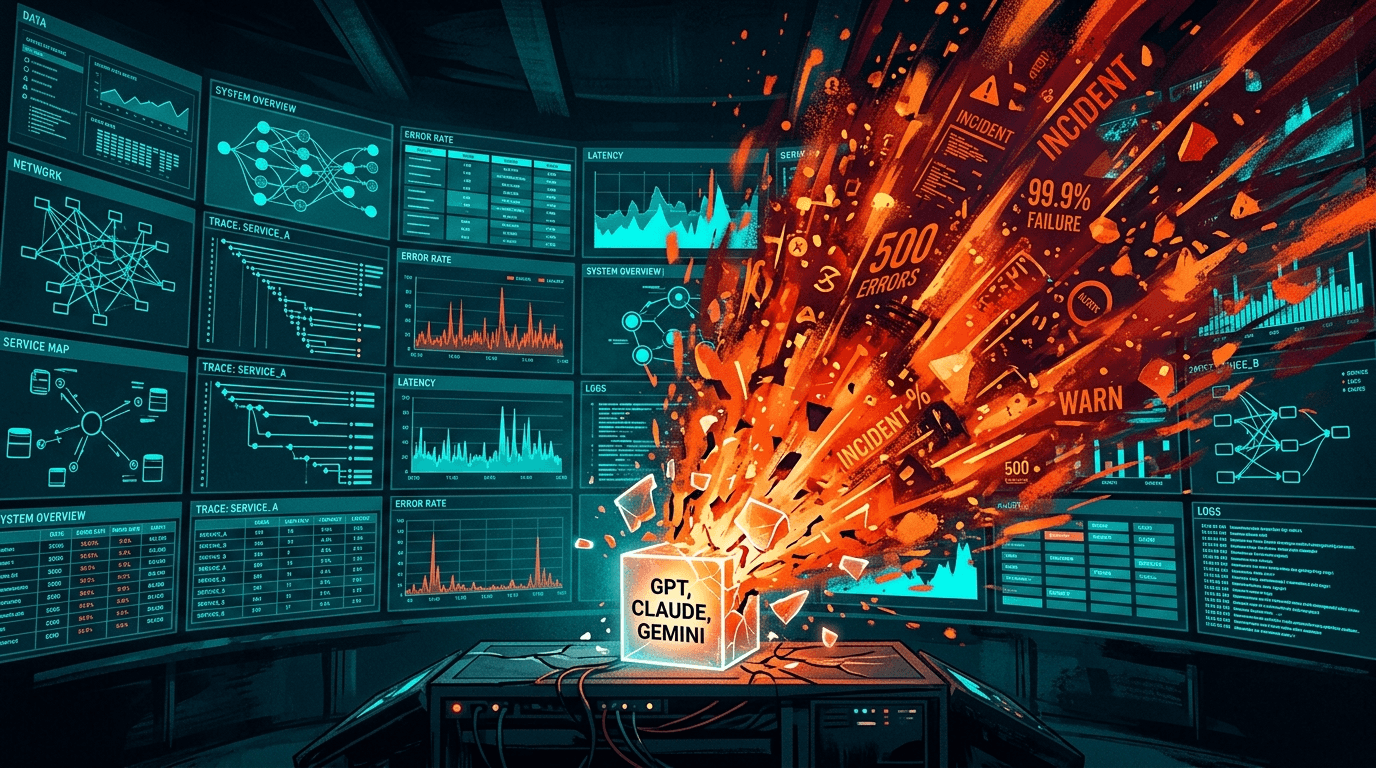
There's a persistent belief in observability right now: put a big enough model on top of your logs and traces, and incident analysis becomes a prompt. Feed it the telemetry, ask "what went wrong?", get an answer.
The math doesn't support this.
The Context Window Arithmetic
A typical OpenTelemetry span, once serialized with trace IDs, span IDs, service name, operation name, status, timestamps, and a handful of resource attributes, runs roughly 200 tokens. A structured log line with severity, body, and trace context lands in the same range. Some are shorter. Spans with large attribute maps or embedded payloads blow past 400.
GPT-5.4, Claude Opus 4.6, and Gemini 2.5 Pro have all converged around 1M tokens of usable context. So:
1,000,000 tokens / ~200 tokens per span = ~5,000 spans.
That's the entire working set. Not per service. Not per minute. Total.
What a Real Incident Looks Like
Consider a payment processing failure in a mid-sized e-commerce platform running 40 microservices on Kubernetes. A single checkout request touches 8-12 services: API gateway, auth, inventory, pricing, payment processor, fraud detection, order service, notification. Each service generates 3-15 spans per request. Call it 60 spans for one checkout.
At 500 requests per second, that's 30,000 spans per second across the checkout path alone. The other 30 services are generating their own telemetry. Background jobs, health checks, cache refreshes, queue consumers. A conservative estimate for the full system: 200,000 spans per minute.
An incident that takes 15 minutes to detect and another 30 minutes to investigate spans a window of roughly 9 million spans and tens of millions of log lines.
5,000 spans is 0.05% of that.
The Pipeline Between Production and the Prompt
This is where it gets worse. Those 5,000 spans don't arrive at the model as a representative sample of your incident. They arrive after passing through a series of filters, each one making decisions about what to keep and what to drop.
Head-based sampling decides at trace initiation whether to record or discard. A 10% sampling rate means 90% of traces never exist in your backend. If the failing request pattern occurs in 1 out of 1,000 requests, there's a real chance the sampled set contains zero examples of the actual failure.
Tail-based sampling improves this by making the keep/drop decision after the trace completes. But tail-based sampling in OpenTelemetry requires a collector that holds spans in memory until all fragments arrive. At high throughput, collectors start dropping spans to stay within memory limits. The spans that get dropped aren't random; they're the ones that arrived during the highest-volume period, which is often the incident itself.
Retention policies in your observability backend add another layer. Datadog, Grafana Cloud, and Dynatrace all apply TTL-based eviction or downsampling. High-cardinality attributes get dropped or truncated on ingest. By the time you're investigating an incident that happened yesterday, the detailed spans from the critical window may already be partially evicted.
Query limits are the final gate. Most backends cap trace search results at 20-50 traces per query. Even if the data exists, the API only surfaces a slice.
So the model doesn't get 5,000 spans from your incident. It gets 5,000 spans that survived sampling, retention, truncation, and query limits. Every stage introduces selection bias. Every stage can silently discard the signal that explains the failure.
The Model Isn't the Bottleneck
The vendors pitching "AI-powered incident analysis" are solving the wrong problem. The model is the most capable component in the entire pipeline. GPT-5.4 and Claude Opus 4.6 are genuinely good at reasoning over structured data when you give them the right data.
The problem is upstream. AI is a fundamental enough shift that bolting a model onto the same observability databases, the same sampling pipelines, the same retention-constrained backends, will not get you there. The infrastructure that feeds the model was designed for human operators: dashboards, alert thresholds, manual queries. It was never built to supply the continuous, complete, context-rich telemetry that AI reasoning actually requires.
It's the instrumentation that didn't capture the right attributes. It's the sampling that discarded the trace you needed. It's the retention policy that evicted the logs from the critical window. It's the query API that returned 20 traces when you needed 2,000.
Improving the model from "good at reasoning" to "great at reasoning" doesn't help when the input is a filtered, sampled, truncated, retention-bounded, query-limited slice of what actually happened.
What Would Actually Help
Instead of building bigger context windows, the gain is in what reaches the model:
- Instrumentation that captures without gaps. If a service is running, it should be producing telemetry. No manual SDK integration that gets skipped for the service that was "going to be temporary."
- Dynamic instrumentation depth. Normal traffic gets lightweight tracing. When error rates spike or latency degrades, instrumentation automatically captures deeper context: full request/response payloads, database query parameters, queue message bodies.
- Sampling that preserves anomalies. Error traces, high-latency traces, and traces touching services that are actively alerting should have a 100% capture rate during incidents, not 10%.
The question for AI in observability isn't "how big can the context window get?" It's "how good is the data that fills it?"
A 1M-token context window filled with the right 5,000 spans could genuinely accelerate incident resolution. The same window filled with whatever survived the pipeline is just faster guessing.
More from the blog.
Stop guessing. Ask production.
One agent. One service. See how Odigos helps answer a production question.